Over the past two years, the keyword in securities firms’ AI infrastructure investment has been “buy”: buy accelerators, stockpile cards and expand data centers, increasing compute capacity year after year. Yet once the cards have been assembled, the real test has only just begun—dispersed cards do not equal production capacity; Tokens actually being produced do. Compute planning is shifting from the one-time investment of “buying and stockpiling accelerators” to the long-term operation of “Token production capacity”: consolidating heterogeneous compute into a unified production line while ensuring that every Token is metered, accounted for and put to effective use. Using RiseUnion’s unified multi-cluster management architecture and platform operations framework, a securities firm has put this approach into practice, bringing clarity to its “two sets of accounts”: supply-side capacity and business operations.
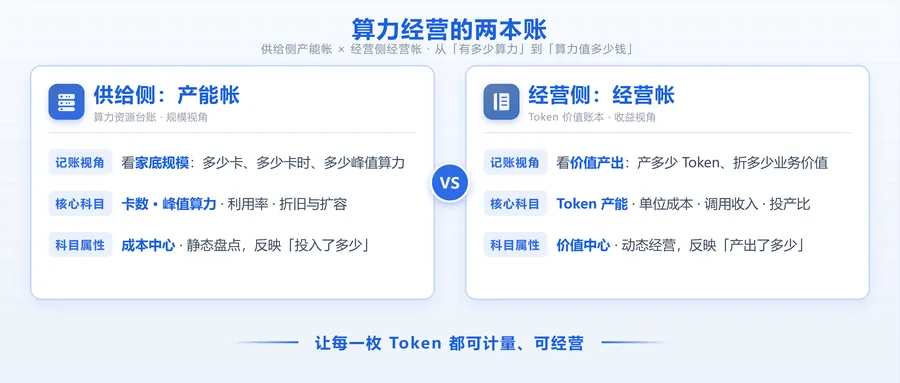
The Supply-Side “Capacity Account”: Turn Dispersed Cards into a Token Production Line
[Pain point] Why are the accelerators we bought not producing enough Tokens?
In production, the firm faced a separation of management and compute domains across data centers, multiple heterogeneous accelerator types and fragmented model access endpoints. Under the traditional approach, each tenant had an exclusive resource pool, preventing idle compute from being shared. Cards were purchased for peak demand, but capacity ran at off-peak utilization; storage and container image infrastructure were also duplicated. Under the logic of buying and stockpiling accelerators, these losses were hidden in reports showing “assets in place.” Viewed through the lens of production capacity, they were all lost Tokens.
[Solution] Implementation: Unified management across data centers brings every card into the capacity pool
-
Reuse existing assets and coordinate heterogeneous resources: a deployment architecture separating the management domain from the compute domain, connected through dedicated lines, directly reuses existing container clusters, image registries, storage devices and identity systems. General-purpose compute and heterogeneous accelerator clusters are centrally managed. Cards from different generations and vendors are abstracted into unified compute units, freeing applications from specific hardware models. This is the first step toward production-oriented capacity: turning scattered machines into one unified production line.
-
A unified gateway and a complete operations loop: an intelligent gateway exposes a single access endpoint and unified key, routing application traffic to the appropriate compute cluster according to model identifiers. Monitoring metrics, alerts and fault migration mechanisms form an end-to-end operations loop. To produce Tokens reliably, the production line must keep running.
-
Pooled sharing and immediate usability: a heavy management model is simplified to one level of isolation in which “each project is a tenant.” Projects share a common resource pool within their quotas to improve utilization. Enterprise single sign-on, real-name verification gates and automatic quotas at registration provide secure access and an environment ready in one click. The key metric for a capacity pool is utilization: the more widely the pool is shared, the lower the cost per Token.
The Business-Side “Operations Account”: Give Every Token an Owner, a Price and an Accounting Record
[Pain point] With capacity in place, why are the accounts still unclear?
As teams in investment research, risk control and quantitative analysis frequently accessed large models and compute, coarse management exposed multiple operational blind spots. Business teams only discovered costs after consumption, with Token use completely disconnected from budgets. Free storage without visible cost encouraged redundant models and data to accumulate, while frequent resource scaling lacked precise mechanisms for additional charges and refunds. Technology departments lacked flexible subsidies for promoting innovative applications, and reconciling compute and model usage across clusters for compliant month-end settlement was difficult. Without an operations account, even abundant production capacity remains an unclear fixed-asset expense.
[Solution] Implementation: Calculate costs across the full lifecycle, pricing, metering and settling compute as production capacity
Based on the actual lifecycle of compute consumption inside the firm, the platform establishes a complete operations loop spanning budget approval, usage metering, incentives and settlement:
-
Upfront cost previews and two budget-control modes: before a team creates a resource or changes its specification, the system previews estimated hourly or monthly costs and price differences in real time. Changes take effect only after confirmation, eliminating blind ordering. Teams with steady day-to-day workloads default to “prepaid: top up before use” to enforce budget limits. Sudden market analysis or temporary problem-solving workloads can switch to “postpaid: use now, settle later,” so business flexibility is not constrained by the current balance. The first principle of operations is to calculate the costs before starting the production line.
-
Precise billing by usage segment and transparent storage charges: compute instances are billed accurately by the hour. Scaling up only adds the price difference for the remaining period, without retroactive charges. When resources are downgraded, stopped or deleted, fees for unused time are automatically returned to the account and a traceable refund record is generated. Storage is billed transparently as “capacity unit price × actual usage time,” with charges stopping immediately on deletion. Clear cost awareness encourages teams to remove redundant data promptly.
-
Automatic balance alerts, shutdown and recovery after top-up: the cost center displays the available balance in real time and issues alerts below a configured threshold. After a depleted balance triggers automatic shutdown, users can scan a code to top up online, with automatic compensation for payment-channel errors and refunds to the original payment method for mistaken top-ups. Resources recover as soon as funds arrive, without manual operations intervention.
-
Support for internal innovation and automatic discounts across clusters: vouchers are issued automatically after registration, successful real-name verification or top-up. At settlement, those expiring first are applied first to compute and model consumption. Administrators can configure billing discounts by workspace or project, with project-level discounts taking priority and no stacking, and automatically synchronize them across member clusters. Pricing displays, bills and invocation records all show discounted details clearly. Discounts are also an operations tool: pricing incentives encourage teams to produce more Tokens and develop more use cases.
-
Three-dimensional billing analysis and a compliant business-finance loop: the cost center and administration console support detailed, transaction-level analysis across “resources, Tokens and wallets,” automatically aggregating monthly bills so that “who spent how much, and where” is clear at a glance. The system also connects the full workflow for initiating contracts from templates, reviewing and stamping them, and managing contract records, as well as online invoice applications, qualification reviews, electronic delivery and paper-invoice shipment tracking. Operating production capacity must ultimately be reflected in financially compliant accounts.
Closing Thoughts
Buying and stockpiling accelerators answers “how much compute do I have?”; operating Token production capacity answers “what is my compute worth?” Through the combination of “supply-side production capacity” and “precise operational cost accounting,” existing users can switch seamlessly to the new workspace without registering again. Their original resources and business data remain intact as they establish a more secure, transparent and convenient financial-grade compute operations system.
About RiseUnion
Beijing RiseUnion Technology Co., Ltd. (RiseUnion) focuses on AI compute management and scheduling. It has completed compatibility certification with more than 10 domestic chip vendors and is a core contributor to the CNCF Sandbox project HAMi. The company is recognized as a national high-tech enterprise and a Beijing specialized and innovative SME, and leads the AIIC Compute Resource Pooling Working Group. It has achieved large-scale production deployments in finance, government and enterprise, defense, transportation, healthcare and other industries.
RiseUnion is committed to making compute as readily available as water and electricity, building an intelligent, controllable and efficient computing foundation for enterprise AI transformation.
For more information, visit riseunion.ai or call 400-605-2336.